The artificial intelligence landscape in October 2026 reflects an industry pivoting from experimental reasoning architectures toward production-grade autonomous infrastructure. Enterprise adoption centers on structured operational integration, while regulatory oversight across major jurisdictions introduces strict compliance verification for large-scale model deployments. Understanding current technological momentum requires separating documented engineering releases from speculative capability forecasts and roadmap leaks.
System architects and corporate planners evaluate advancements by examining verifiable benchmark stability, infrastructure availability, and deployment risk. Distinguishing between confirmed production systems and unverified vendor promises remains essential for sustainable technological implementation.
Frontier Foundation Model Developments
Frontier model discussions in early October center on multi-token prediction improvements, asynchronous chain-of-thought verification, and reduced latency across complex reasoning tasks. Engineering teams prioritize reliable tool invocation over brute-force parameter scaling, altering standard compute allocation during post-training stages.
Industry roadmap tracking highlights discussions around prospective systems referred to in speculative filings as GPT-6 Astra and iterative variants like GPT-6.1 Sol. While internal leaks suggest these architectures target autonomous multi-step error correction and specialized agent routing, OpenAI says production availability remains subject to rigorous safety evaluations. Independent validation of these architectures remains unconfirmed by external benchmarking consortia, requiring organizations to treat capability claims with measured scrutiny.
Simultaneously, developer channels monitor updates regarding Gemini Argon from Google DeepMind, designed to operate natively across dense real-time sensor streams. Early access documentation points toward specialized processing layers for structured enterprise data, though widespread general availability across standard developer tiers has not concluded. Pricing considerations around inference expense continue to evolve, with organizations evaluating baseline computational expenditure per million output tokens across mission-critical workloads.
| Platform Project | Development Status | Verification Level | Primary Architectural Focus |
| GPT-6 Astra | Unannounced | Speculative Leak | Multi-step autonomous reasoning and recursive code correction |
| GPT-6.1 Sol | Roadmap Phase | Unverified Report | Low-latency task planning across persistent agent networks |
| Gemini Argon | Early Testing | Confirmed Pilot | Streaming multimodal context processing and enterprise tool use |
| Claude Next Core | Internal Safety | Vendor Statement | Constitutional self-monitoring during complex tool orchestration |
Model selection decisions depend heavily on operational stability rather than theoretical peak performance. Organizations maintain fallback pipelines to established reasoning engines while monitoring frontier development stages.
Autonomous Agents in Enterprise Workflows
Autonomous agent frameworks have progressed from simple chat assistants into persistent background workers capable of coordinating multi-system transactional workflows. These agent clusters manage routine supply chain adjustments, invoice reconciliation, and cross-departmental documentation without constant manual prompting.
The operational value of an agent system rests on its underlying decision layer, which maps natural language directives into validated API calls. Enterprise data integration remains the primary hurdle, as legacy databases frequently lack the semantic metadata required for autonomous discovery. Organizations that succeed in agent deployment implement strict programmatic boundary gates to constrain autonomous execution within predefined operational thresholds.
Despite steady adoption, reliability inconsistencies continue to generate friction in production deployments. Unmonitored agents can compound minor logic errors into significant operational bottlenecks when running unbounded loops across interconnected software suites. Implementing human-in-the-loop checkpoints at critical state transitions reduces the risk of administrative errors.
Autonomous systems require deterministic policy controls at the API gateway rather than probabilistic guardrails within prompt contexts. Hardcoded permission limits prevent unexpected state modifications across production databases.
Operational stability improves when agent responsibilities remain narrowly scoped to discrete domain tasks. Broad, open-ended operational roles lead to higher failure rates and complicated audit trails.
Automated Code Generation and Developer Tools
Automated software construction environments represent one of the most commercially mature applications of generative intelligence. Modern coding tools now routinely handle multi-file refactoring, comprehensive test generation, and automated documentation across enterprise codebases.
Development teams increasingly interact with synthetic code through automated review queues rather than inline editor prompts. This workflow shift allows senior engineers to focus on architectural topology and security boundaries while automated systems draft implementation details. Nevertheless, maintaining long-term repository health requires rigorous automated static analysis to catch subtle architectural drift.
A notable performance gap persists between initial prototype synthesis and production maintenance tasks. When dealing with obscure internal frameworks or deeply nested dependencies, automated systems often generate plausible but non-functional logic. Code quality metrics must emphasize runtime durability and test coverage rather than raw generation velocity.
- Automated unit test synthesis matching documented acceptance criteria across pull requests.
- Continuous vulnerability scanning targeting third-party dependency chains before build integration.
- Semantic code translation supporting legacy system migration into modern execution languages.
- Synthetic documentation generation aligned directly with live API endpoint definitions.
- Multi-repository structural refactoring coordinated through declarative architectural rules.
Engineering leadership teams track error reproduction rates to identify when automated code generation introduces hidden technical debt. Rigorous review policies remain non-negotiable across mission-critical systems.
Datacenter Infrastructure and Cloud Computing Shifts
Physical infrastructure demands continue to dictate the deployment velocity of next-generation artificial intelligence platforms. Hyperscale operators face unprecedented energy and cooling constraints, spurring substantial capital reallocation toward geographically distributed computational clusters.
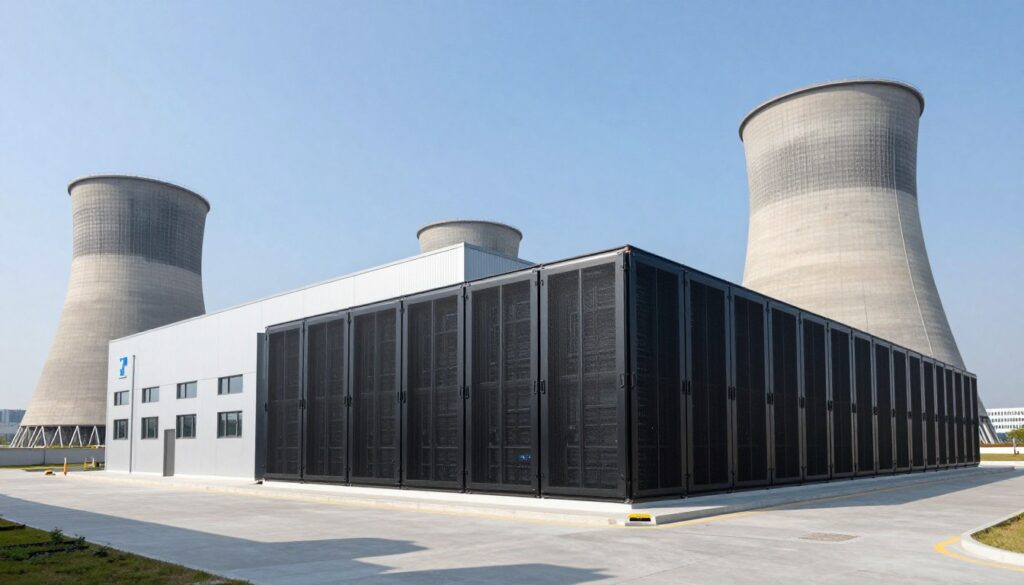
Data center capacity expansion increasingly depends on localized power agreements, including direct contracts with modular nuclear and geothermal generation facilities. The geographical footprint of frontier cluster training has expanded outside traditional technology corridors to capture available electrical capacity. This spatial dispersion necessitates complex distributed training algorithms that remain resilient across higher inter-datacenter network latency.
Cloud providers restructure procurement frameworks around long-term capacity reservations rather than on-demand spot instances. Enterprise access to cutting-edge accelerator clusters requires multi-quarter commitments, prompting organizations to optimize existing model weights through quantization and distillation. Efficient parameter usage reduces reliance on scarce hardware tiers.
Electrical Grid Interconnection
Facilities prioritize sub-station proximity and dedicated high-voltage grid connections to sustain steady power delivery during intensive training runs.
Liquid Immersion Cooling
High-density compute racks rely on advanced liquid thermal dissipation systems to manage heat profiles without excessive water consumption.
Infrastructure capital expenditure remains concentrated among a small tier of global cloud providers. Secondary operators focus on regional sovereign clusters designed to meet local data residency mandates.
Cybersecurity Applications and Defensive Systems
The cybersecurity domain presents an evolving operational balance between synthetic offensive vectors and automated network defense systems. Autonomous vulnerability discovery tools systematically probe application interfaces, requiring defensive response protocols to operate at machine speed.
Cyber defenders leverage specialized behavioral analysis models to identify novel infiltration patterns that bypass signature-based detection. These defensive frameworks ingest real-time network telemetry, autonomously isolating compromised endpoints before threat actors execute lateral network movement. The integration of synthetic log summarization accelerates incident investigation workflows for security operations teams.
Simultaneously, offensive automation tools lower the operational barrier for executing complex multi-stage social engineering campaigns. Automated voice synthesis and contextual text generation enable threat actors to produce personalized phishing material at unprecedented volume. Security awareness initiatives must adapt to counter materials that display zero traditional grammatical or contextual anomalies.
Defensive security architectures must validate model integrity through cryptographic verification. Manipulated training data or adversarial prompt injection can degrade anomaly detection thresholds across internal network monitors.
Security engineering requires continuous adversarial testing to uncover latent vulnerabilities within model-driven monitoring tools. Organizations maintain isolated offline recovery infrastructure to protect against automated credential compromise.
Regulatory Compliance and Global Policy Updates
Global regulatory frameworks have transitioned from preliminary guidance principles into enforceable statutory oversight. Operating across multinational jurisdictions requires organizations to establish auditable governance pipelines for tracking model origin, data provenance, and system behavior.
The enforcement timeline of major legislative mandates, including comprehensive regional governance rules, introduces mandatory technical documentation for high-risk artificial intelligence implementations. State compliance audits scrutinize bias mitigation measures, human oversight mechanisms, and environmental resource reporting. Organizations failing to establish verifiable compliance logs face severe administrative penalties and operational injunctions.
Transatlantic policy coordination remains uneven, producing distinct compliance standards between North American and European operational environments. While certain administrative jurisdictions emphasize market innovation and decentralized standards, others demand formal pre-deployment conformity assessments. Navigating this fragmented regulatory landscape requires adaptable compliance architectures that support modular governance enforcement.
- Mandatory risk classification for automated decision engines impacting public access.
- Standardized documentation of copyrighted materials within training corpora.
- Periodic third-party algorithmic bias evaluations across hiring and lending pipelines.
- Watermarking and cryptographic verification for synthetic public communications.
Direct Regulatory Mandates
- Comprehensive data lineage tracking from initial ingestion to model inference.
- Granular role-based access limits for autonomous agent execution tools.
- Automated incident recording capturing anomalous system logic and outputs.
- Continuous evaluation of third-party model dependencies and API providers.
Internal Enterprise Controls
Corporate legal departments collaborate closely with technical architects to prevent compliance bottlenecks during product release cycles. Standardized model reporting templates simplify cross-jurisdictional filing obligations.
Open-Source Community Releases and Frameworks
The open-source ecosystem provides a resilient counterweight to proprietary commercial platforms, offering developer communities verifiable model weights and customizable training recipes. Collaborative repositories support rapid innovation in parameter-efficient fine-tuning and localized deployment.
Hugging Face and decentralized developer networks continue to host specialized distilled models that compete effectively with larger proprietary systems on structured tasks. Community efforts focus heavily on synthetic dataset curation, allowing smaller parameter architectures to achieve competitive reasoning benchmarks. Open weights provide developers with complete operational visibility, eliminating unexpected API deprecation risks.
Licensing frameworks within the open community have diversified, reflecting nuanced commercial use restrictions and safety obligations. Permissive open-source licenses remain popular for academic exploration, while hybrid commercial licenses restrict direct competitive hosting by cloud infrastructure providers. Developers evaluate license language carefully to verify that commercial derivative works comply with community distribution clauses.
Localized Quantization
Advanced weight compression techniques allow capable reasoning models to execute locally on consumer-tier workstation hardware without external network dependencies.
Curated Synthetic Data
Community-driven synthetic data pipelines enable targeted domain training while substantially reducing reliance on unverified internet web scrapes.
Modular Fine-Tuning
Low-rank adaptation adapters allow organizations to inject specialized proprietary knowledge into foundational weights without altering the underlying core parameters.
Local inference adoption expands rapidly across healthcare and defense sectors where data privacy regulations prohibit external cloud routing. Open models provide the architectural independence required for sensitive data handling.
Productivity Platforms and Knowledge Architecture
Enterprise productivity suites have deeply embedded machine learning interfaces into daily corporate communication and document management workflows. Knowledge workers interact with automated drafting, summarization, and spreadsheet analysis as standard operating functions.
Integration within ecosystems such as Microsoft 365 copilot environments demonstrates both the utility and limitations of automated workplace assistance. Contextual indexing across email threads, calendar schedules, and internal documents provides immediate informational synthesis. However, the quality of synthetic summaries depends entirely on the organization’s underlying document management hygiene.
When organizations deploy productivity assistants without rigorous permission boundaries, automated search mechanisms can expose confidential executive discussions to unauthorized staff tiers. Implementing precise access control lists across corporate storage repositories prevents unintended data leakage through conversational interfaces. Structured enterprise knowledge layers require continuous maintenance to prevent outdated documentation from skewing automated outputs.
Operational Advantages
- Rapid synthesis of multi-source document archives into coherent briefing summaries.
- Automated meeting transcription and contextual action-item extraction across team channels.
- Accelerated drafting of standardized business proposals and technical specifications.
Operational Limitations
- Potential dissemination of stale or conflicting internal documentation via chat outputs.
- Accidental exposure of restricted corporate files through unsegmented search indexes.
- Over-reliance on synthetic drafts leading to generic internal communications.
Effective knowledge management strategies combine semantic indexing with strict access verification. Regular audit cycles maintain organizational alignment across automated productivity platforms.
Analytical Review of Emerging Industry Trends
A comprehensive assessment of AI News October 2026 highlights a decisive transition from exploratory model experimentation to disciplined capital allocation. Enterprise leadership teams evaluate computational platforms through the lens of return on investment, operational resilience, and compliance manageability rather than novelty.
The news week cycles throughout early October confirm that computing power constraints remain the central governing factor of technological pacing. While algorithmic refinements continue to yield efficiency gains, physical grid access and thermal management define the ceiling of frontier cluster development. As a consequence, hardware-software co-design has emerged as the defining engineering priority for leading technology providers.
Simultaneously, the industry faces an ongoing challenge in separating verified technical breakthroughs from aspirational promotional material. A significant portion of public commentary surrounds internal project code names and speculative capabilities that lack empirical validation. Organizations that base strategic roadmaps on verifiable production benchmarks achieve greater operational durability than those pursuing unconfirmed technological forecasts.
Sustainable technology adoption requires validating model output stability across real-world edge cases. Theoretical benchmark rankings provide an incomplete picture of total operational maintenance requirements.
Strategic success in the current environment demands balancing rapid internal tooling adoption with robust defensive governance. Organizations that institutionalize verification protocols remain best positioned to capitalize on sustained engineering breakthroughs.
Frequently Asked Questions
What distinguishes confirmed AI releases from roadmap speculation?
Confirmed releases feature publicly accessible APIs, downloadable weights, verified documentation, and independent reproducibility reports. Speculative developments exist solely as unverified corporate leaks, trademark applications, or executive forward-looking statements lacking technical validation.
How do organizations manage computational costs per million output tokens?
Organizations reduce operational token expenses through model routing architectures, prompt caching, quantization, and domain-specific model distillation. Deploying smaller, specialized models for routine classification tasks preserves frontier reasoning budgets for complex edge cases.
Why are autonomous agents subject to strict operational boundaries?
Autonomous agents operating in production environments can trigger cascading systemic errors when executing unconstrained API calls across enterprise software suites. Establishing deterministic permission boundaries at the gateway level prevents unintended financial, administrative, or structural data modifications.
What role does datacenter electrical capacity play in AI development?
Electrical grid availability governs the speed and scale at which modern compute clusters can expand physical training and inference operations. Energy access constraints have decentralized cluster locations, prioritizing dedicated power partnerships over geographic proximity to corporate headquarters.
How do global governance policies impact enterprise AI integration?
Enforceable governance frameworks require enterprises to maintain auditable records of training data provenance, algorithmic risk mitigation, and security testing protocols. Non-compliant deployments risk substantial regulatory fines, mandatory operational pauses, and reputational impairment.
Summary of October 2026 Developments
The progression of artificial intelligence in October 2026 demonstrates that operational durability, regulatory compliance, and physical infrastructure constraints outweigh raw parameter scaling. Success in deploying intelligent systems depends on disciplined verification, transparent architecture, and continuous risk management across corporate pipelines.
Comments are closed